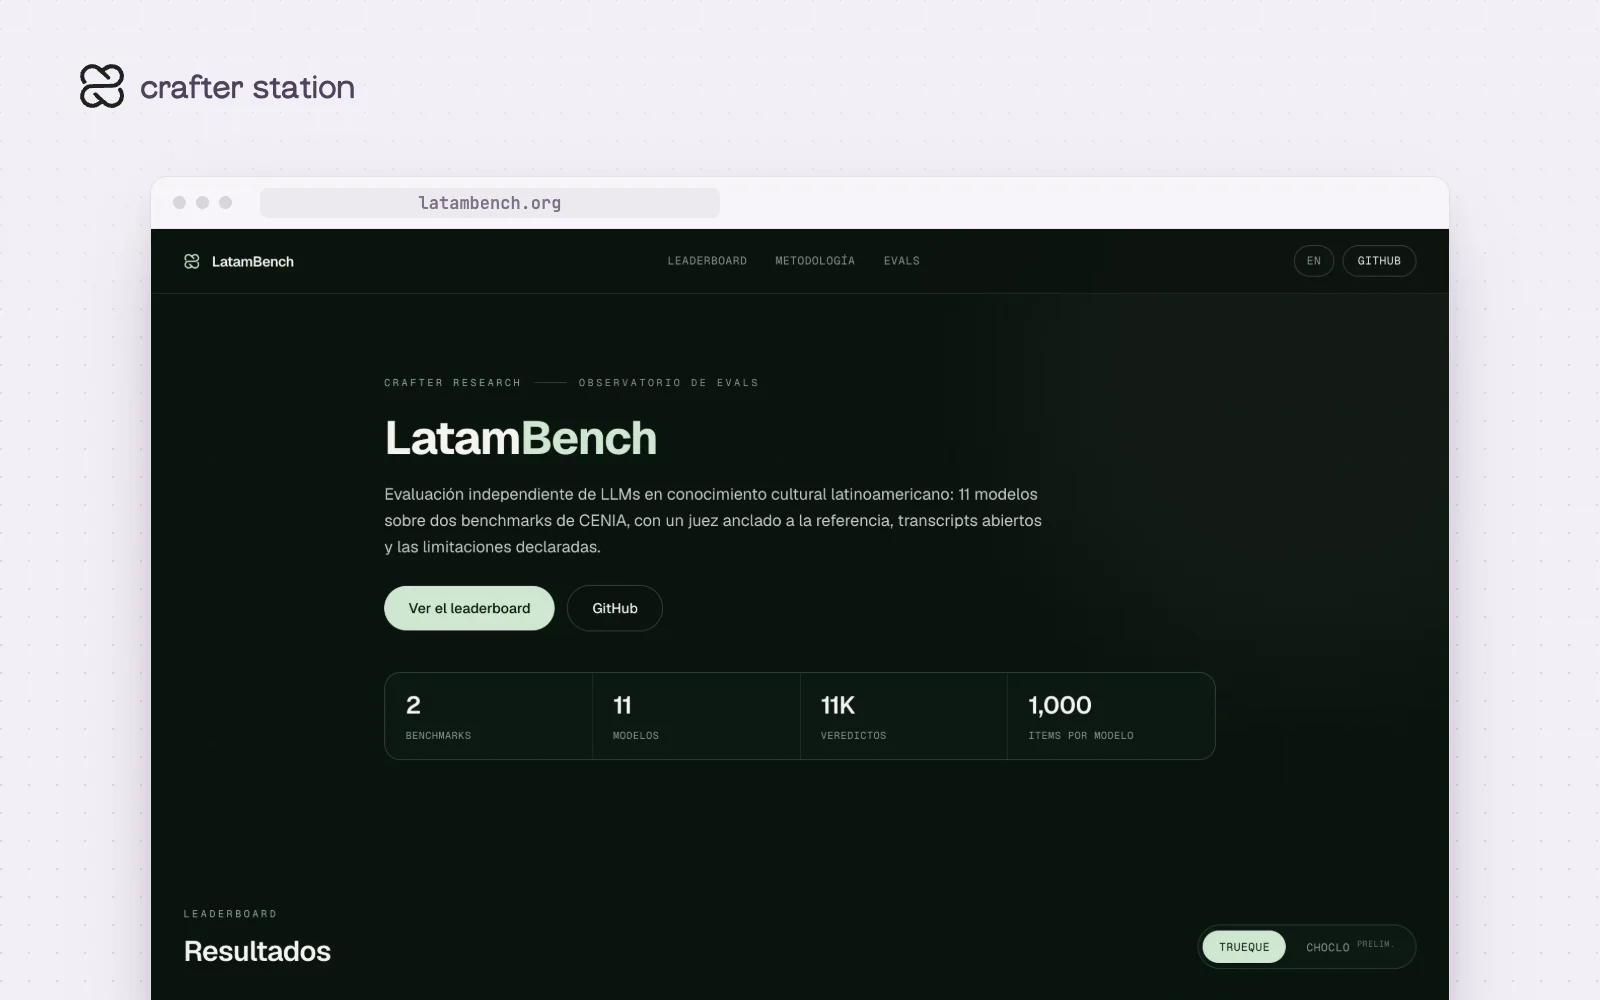
LatamBench is an independent leaderboard for how well language models know Latin American culture. It reruns the Trueque and CHOCLO benchmarks with a judge anchored to the reference answers, publishes every transcript and audits the benchmarks along the way. It is built by Crafter Research and lives at latambench.org.
Three numbers per model#
Raw accuracy counts an honest "I don't know" the same as an invented answer. LatamBench splits every model's result into correct, abstention and hallucination, so you can see which models make things up when they fail. On CHOCLO, the regional LatamGPT model hallucinates on 53.2% of items, the highest on the board.
Two benchmarks, audited#
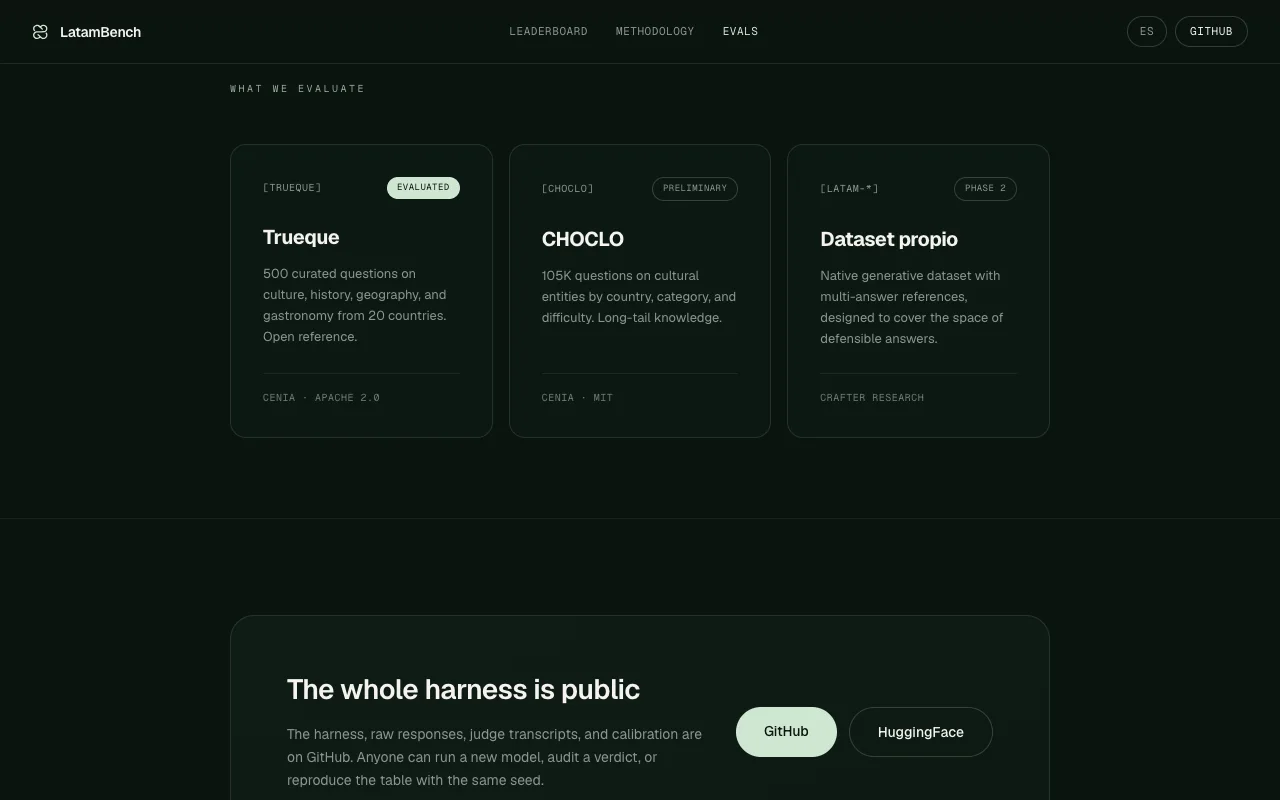
Trueque has 500 curated questions on culture, history, geography and food from 20 countries. CHOCLO covers long-tail cultural entities by country, category and difficulty, and its results are marked preliminary because the judge calibration covers Trueque only.
Try it#
Read the leaderboard at latambench.org. To audit a verdict or run a new model, the harness, raw responses and judge transcripts are in the GitHub repository, with seed 42 and temperature 0 so the table reproduces.